
data-kraken

Data Kraken
A command line tool that fetches info about users, commits, repositories, Docker images and npm dependencies from GitHub.
Prerequisites
This tool runs with Node.js. Make sure you have an up-to-date version installed.
Preparation
You need to have a personal access token for the orgs and repositories on GitHub that you want to examine.
Getting a token – click here for a step by step guide
- Go to your GitHub token settings page:
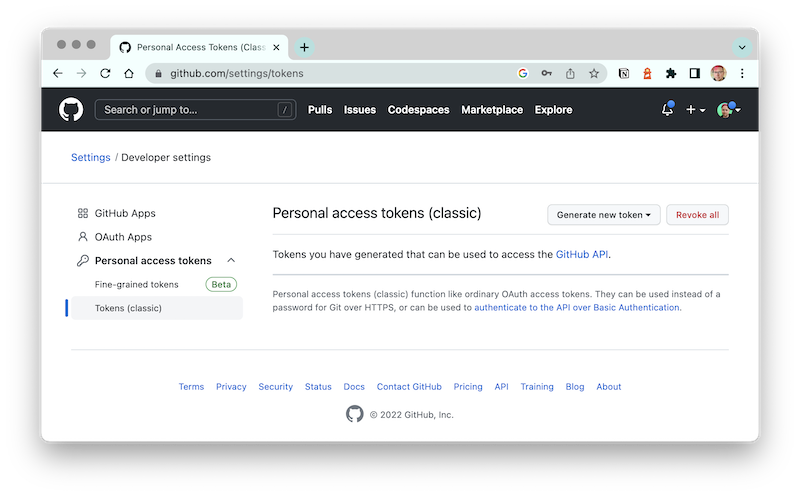
- Click on “Generate new token (classic)”
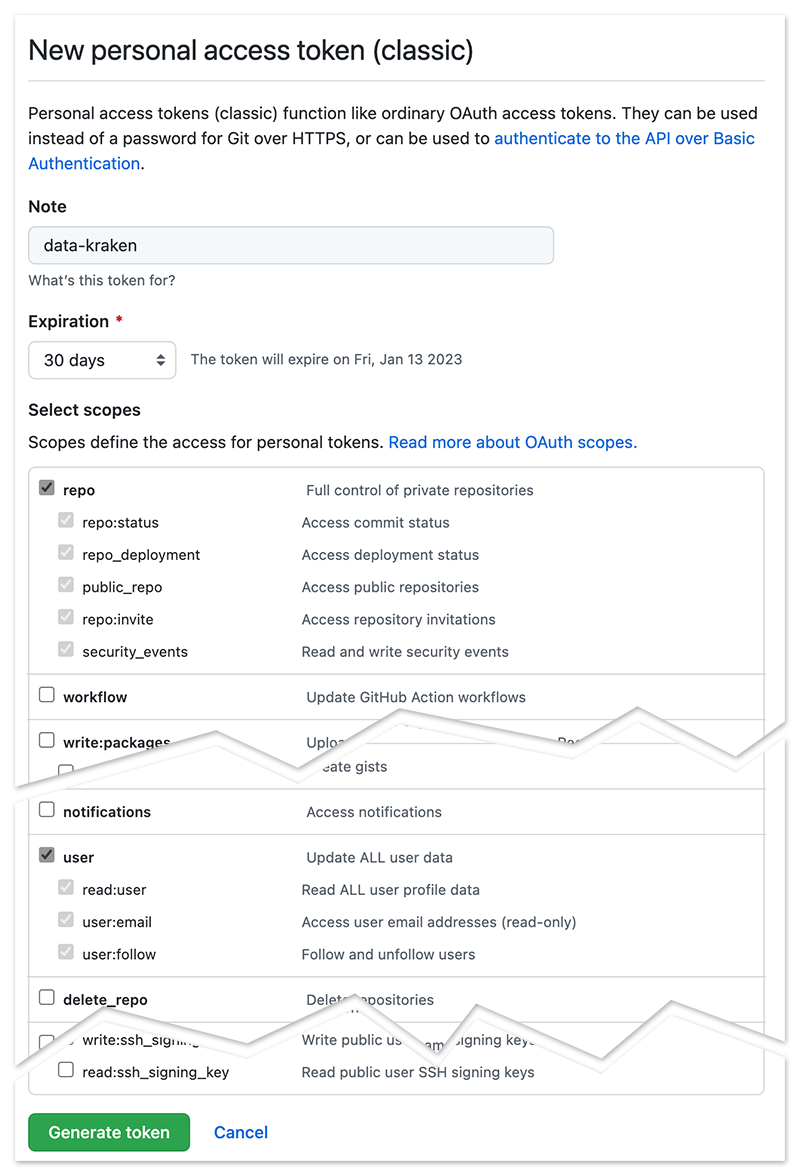
- Enter any name you find suitable
- Tick the checkboxes for access to “repo” and “user”
- Confirm with “Generate token”
- Copy the personal access token to a safe place for later use
Refer to the instructions on GitHub for further information on this.
Installation
Install the data-kraken as a global command line tool using npm like so:
npm install -g data-krakenCreate a configuration file
Before you can use data-kraken, you have to set it up so that it knows yours the GitHub personal access token you've created (see chapter Preparation).
For this, you create a configuration file with in your home directory, like so:
echo DK_ACCESS_TOKEN=personal-access-token123 > $HOME/.data-krakenGitHub Enterprise users
By default, data-kraken uses the API of the public GitHub, github.com. If your company
is hosting its own GitHub Enterprise instance, like we do at Adevinta, add the
DK_BASE_URL option to your .data-kraken config file, for example:
DK_BASE_URL=github.es.ecg.toolsHow to run
With the access token in place as described in the previous chapters, run the data-kraken on the command line like so:
data-kraken(this will display a help message to get you on your way)
Getting the latest version
By default, once installed, data-kraken will always run the locally installed version. If you don't want to miss the latest features, run this every once in a while to get the latest version:
npm update -g data-krakenUsage examples
Tech Debt
Shows a technical debt score for one or more GitHub repositories.
data-kraken tech-debt --org mobile-de --repo consumer-feThe repository parameter is optional:
- if repository is provided, the output will show the score along with some improvement hints
- if repository is omitted, the output will show a list of all the repos in the org, ranked according to their tech debt score
More info
Run --help for more info on the tech-debt command:
data-kraken help tech-debtGuilds
Shows the guilds associated with repos – backend, frontend, data, qa, android, ios or devops.
data-kraken guild --org mobile-de --repo consumer-feThe repository parameter is optional:
- if repository is provided, the output will show the repo's associated guilds
- if repository is omitted, the output will show a list of all guilds found in the org, along with the repos associated with them
Many commands, including the guild command, have a --guilds option that lets you specify guilds. The
generated output will then only show data from repos associated with the specified guilds.
More info
Run --help for more info on the guild command:
data-kraken help guildInactive
Shows the level of inactivity of GitHub repository. The inactivity score is a value from 0 to 100, 0 being a repo that currently gets updated every day and 100 being a repo that has not been updated in a very long time.
data-kraken inactive --org mobile-de --repo consumer-feThe repository parameter is optional:
- if repository is provided, the output will show the repo's inactivity score along with additional info on how the score is componsed
- if repository is omitted, the output will show a list of all the repos in the org, ranked according to their level of inactivity
More info
Run --help for more info on the inactive command:
data-kraken help inactiveDocker images
Shows the Docker images used in the specified GitHub org and repository, found in a search of all the Dockerfiles in each repo.
data-kraken docker-images --org mobile-de --repo consumer-feRepository is optional, if omitted, the whole org is searched.
Search expressions
You can pass a regular expression to match the images against. In the simplest usage example, the expression can just be a search term:
data-kraken docker-images --org mobile-de nodeThis will give you a list of repositories that use a Node.js image.
More advanced example:
data-kraken docker-images --org mobile-de "^.+/shared/node1[46].+$"This will list all the repos that use dock.es.ecg.tools/shared/node14 or dock.es.ecg.tools/shared/node16, but not dock.es.ecg.tools/shared/node12.
- See also: Regular expressions
More info
Run --help for more info on the docker-images command:
data-kraken help docker-imagesNpm packages
Shows the npm packages that repositories are dependent on according to their package.json files.
data-kraken npm-packages --org mobile-de --repo consumer-feRepository is optional, if omitted, the whole org is searched.
Search expressions
You can pass one or two regular expressions to match the package names or versions against. In the simplest usage example, the expression can just be a search term:
data-kraken npm-packages --org mobile-de react…gives you results for packages that have “react” in them (e.g. react, react-dom, react-router, etc.).
More advanced example:
data-kraken npm-packages --org mobile-de ^react$ "^[~^]*1[68]{1}"…gives you results for precise package “react” with major versions 16 or 18.
- See also: Regular expressions
More info
Run --help for more info on the npm-packages command:
data-kraken help npm-packagesRepos
Shows info about the repositories a user contributed to in “pretty print” on the console:
data-kraken repos patrick-hundYou can use the --org option to constrain output to a specific GitHub org:
data-kraken repos --org mobile-de patrick-hundYou can specify multiple users:
data-kraken repos patrick-hund daniel-korger uwe-loydl- Caveat: Data time range
More info
Run --help for more info on the repos command:
data-kraken help reposFiles
Shows info about what kinds of files the user modified (frontend or backend):
data-kraken files patrick-hundAs with the repos command, you can specify multiple users and a GitHub org. In addition, you can also constrain output to a specific repository:
data-kraken files --org mobile-de --repo consumer-fe nina-maass- Caveat: Data time range
More info
Run --help for more info on the files command:
data-kraken help filesOptions
CSV output
To facilitate importing the output into a Google Sheet, you can specify CSV format:
data-kraken repos --format csv patrick-hund…or…
data-kraken files --format csv patrick-hundThis is particularly useful when using multiple users. You can pipe a list of usernames into data-kraken using xargs and store the output in a CSV file, like this:
cat users.txt | xargs data-kraken files --format csv > files.csvYou can then upload and import the CSV file into Google Sheets.
- See also: CSV date format
JSON output
You can also have data-kraken deliver its output in JSON format, for example:
data-kraken npm-packages --org mobile-de --format jsonVerbose output
All commands support a flag for getting more verbose output:
-v or --verbose
The effect of using verbose mode is different depending on the command and the format type.
Caching
When executing a command, data-kraken does a lot of requests to the GitHub API, which can take a long time. Be patient when executing a command that you haven't used before!
For subsequent command executions, data-kraken uses cached data from previous API calls to speed things up.
The time to live of the caching can be configured through the environment variable DK_FETCH_CACHE_TTL. You can
set it in the .data-kraken config file in your home directory. In
.data-kraken.defaults, this is set to 86400000 milliseconds, which is one day.
Additional notes and caveats
Data time range
For commands related to users (e.g. repos, files), data-kraken fetches commit data of the users.
We fetch data from GitHub as far back as it is allowed to by constraints of the GitHub API. This is usually data for around two weeks, depending on how active the user was (less activity – data ranges further back in time).
Regular expressions
Some hints on how to use regular expression with commands that support them (e.g. docker-images , npm-packages):
- Specify regular expressions without enclosing forward slashes
- Providing regular expression flags (g, i, u, etc.) is not supported
- The search is always case-insensitive
- Complex regular expressions need to be quoted, otherwise your shell will complain because it tries to evaluate the expression
CSV date format
For commands that create CSV data with times in them (e.g. repos, files), importing the CSV
file in Google Sheets works best if you set the DK_LOCALE and DK_TIME_ZONE options in the .data-kraken file
in your home directory to the locale and time zone your Google Sheets is set to. Then dates and times will be
imported properly as dates you can calculate with rather than mere strings.
If your Google Workspace is in German, for example, you want to specify DK_LOCALE=de-DE. If you are located in
Toronto, you want to specify DK_TIME_ZONE=EST.
Default locale is English / Great Britain (en-GB) and Barcelona / Berlin / Amsterdam time (CET).
Contributing
You are most welcome to fork this repository and create a pull request. The following will hopefully get you on your way.
How to install for development
- Check out the source code
- Use correct Node.js version:
nvm use- Install dependencies:
yarn install- Create .data-kraken config file:
cp .data-kraken.example .data-kraken- Uncomment the line with
DK_ACCESS_TOKENin the .data-kraken file, replace the value with your personal GitHub access token (instructions)
Running the script
You can run the script with node src/dataKraken.mjs. For your convenience, there is also an npm script that
does this, with debugging already enabled.
Configuration
To determine the tech debt score, the program analyses the Dockerfiles and package.json files of the repositories and assigns tech debt scores for dependencies that are outdated or banned. The algorithm uses a YAML config file to do this:
Tests
This package uses Jest for automated testing.
Running tests
To run unit test:
yarn testStyle considerations
Write unit tests mostly for low-level functions that have lots of different input to make sure that they return
the expected result. Use test and test.each instead of describe and it.
- Code example: getTechDebtScore.test.js
Terminating with error
Whenever the program encounters a situation where it can't continue, e.g. network errors from API request
attempts, it should terminate with an error code. Use the function die in these cases, supplying an error
message:
import die from "./utils/die.js";

die("Failed to execute command");
Using the GitHub API
The codebase provides a package with utility functions for fetching data from the GitHub API.
Main API functions
The main function for fetching data are:
- fetchResult – given a REST API path and an optional result page, fetches the result from that path
- fetchSearchResult – given a search query and an optional result page, fetches search results
Additional API utilities
This program includes numerous ways to reduce the number of requests to the GitHub API while making it resilient against connection problems and improving performance.
If you implement additional commands that fetch data from GitHub, you need to use these the same way the existing commands do:
- inBatches – executes fetch commands in batches rather than executing them all at once
- withPagination – fetches paged results one page after another
- withRetry – retries API requests if they fail
- fetchWithCache – caches fetch results using the local file system; note: this is already built-in into fetchData, so you'll only need this when implementing your own fetch function ( see Caching)
Debugging
You can turn on a debug logger through the environment variable DEBUG, example:
DEBUG=* yarn data-kraken docker-images --org mobile-deThis will print log statements to the console that are created through the log function.
The asterisk argument in the above example means show all log statements; you can only show specific log statements by specifying a logger name.
The logger name is the relative path to the logging JavaScript module, prefixed with data-kraken:, with forward slashes replaced by colons and without the file extension.
For example, the logger name for module src/commands/dockerImages/run.js is
data-kraken:commands:dockerImages:run, and you can show only log statements from this module with this command:
DEBUG=data-kraken:commands:dockerImages:run yarn data-kraken docker-images --org mobile-de- See also: debug lib documentation on GitHub
Object logging depth
Objects are logged only up to a certain depth. You can increase this depth with the environment variable
DEBUG_DEPTH.
Adding log statements in the code
You can add log statements to any module using debug, like this:
import createLogFunction from "./utils/createLogFunction.js";

const log = createLogFunction();

log("I'm a happy camper");
The logger name will be set to “data-kraken” automatically. You can override this behaviour by providing a name
as a string argument to createLogFunction (recommended!):
const log = createLogFunction("my:awesome:logger");In this case, the logger name you provide is prefixed with data-kraken:, i.e. the resulting logger name will be
data-kraken:my:awesome:logger.
If you intend to leave the log statements in the code, please use sensible names according to the conventions of the debug library. Recommended is the path to the logging JavaScript module, with slashes replaced by colons, without file extension.
Example:
If your module's path is src/command/myCommand/doSomething.js, initialize a logger with this statement:
const log = createLogFunction("command:myCommand:doSomething");Publishing a new package version
Prerequisites
To be able to publish, you need to have the permission on npmjs.org. Ask one of the maintainers to grant you the access rights.
Versioning
This project uses semantic versioning, a.k.a. SemVer. If you're not familiar with the concept, please read up on it.
In a nutshell:
- If your new release contains only bugfixes, publish a patch version (e.g. old version 1.0.0 → new version 1.0.1)
- If your new release contains new features that are compatible with all existing features, publish a minor version (e.g. 1.0.0 → 1.1.0)
- If your new release contains new features that are not compatible with all existing features (also known as “breaking changes”), publish a major version (e.g. 1.0.0 → 1.0.0)
Beta versions are suffixed with -beta.x, where x is a number starting at zero that is incremented with every
beta release.
Beta versions
Before you publish a final version of the package, make sure you test everything with a beta release.
- Make sure tests pass:
yarn test - Bump the version number in package.json – example:
"version": "2.0.0-beta.0" - Bump the version number in src/dataKraken.mjs – example:
.version("2.0.0-beta.0") - Build the bin file (in dist directory*)*:
yarn build - Run the publish command:
yarn npm publish --tag beta - Verify that it worked:
npx data-kraken@beta --version
Final versions
When you are confident your new version is ready for the public at large, follow the same steps as
above, but this time, without the beta parts:
- Make sure tests pass:
yarn test - Bump the version number in package.json – example:
"version": "2.0.0" - Bump the version number in src/dataKraken.mjs – example:
.version("2.0.0") - Build the bin file (in dist directory*)*:
yarn build - Run the publish command:
yarn npm publish - Verify that it worked:
npx data-kraken@latest --version
License
MIT license – copyright 2022 mobile.de GmbH