
wgpu-kit


Creative-coding GPU toolkit for the browser. 200,000-particle physics at 120fps — in 5 lines of code. All the WebGPU boilerplate — device, buffers, pipelines, dispatch, double buffering, readbacks, error line-mapping — wrapped into two simple API layers.
API Reference · 中文文档 · LIVE DEMO
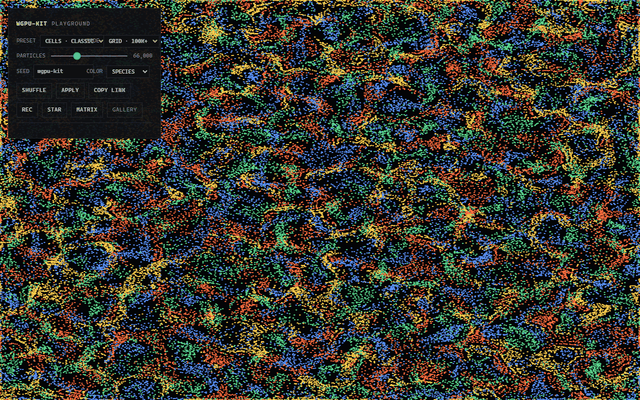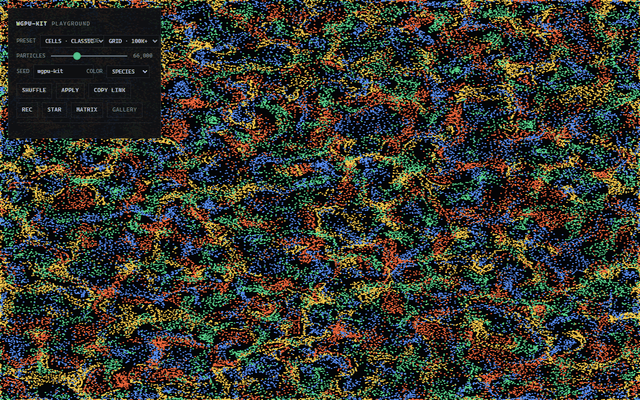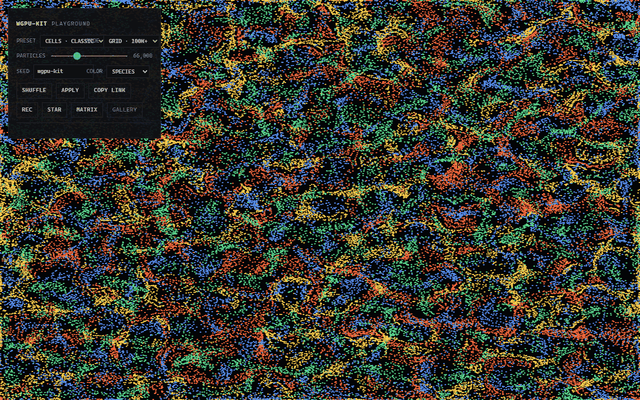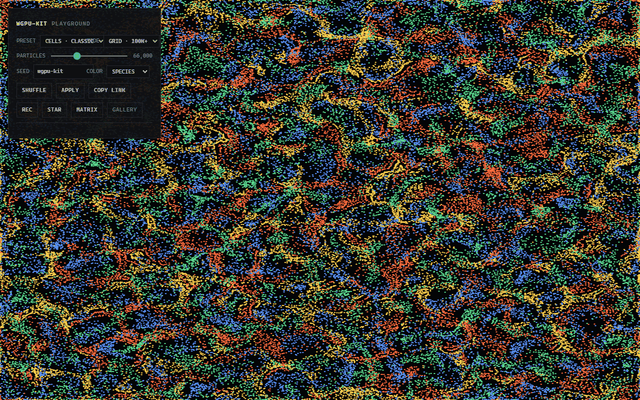
Quick start
npm i wgpu-kit100,000 particles in 5 lines:
import { particles } from 'wgpu-kit';

const sim = await particles({ count: 100_000, forces: 'cells' });
await sim.attach(canvas);
function frame() { sim.tick(); requestAnimationFrame(frame); }
frame();
Custom GPU compute — you only write the per-element function:
import { elementKernel, Buffer } from 'wgpu-kit';

const pos = await Buffer.create('vec2f', 100_000);
const vel = await Buffer.create('vec2f', 100_000);

const integrate = elementKernel({
  state:   { pos: 'vec2f' },
  inputs:  { vel: 'vec2f' },
  uniforms: { dt: 'f32' },
  code: `
    fn userFn(idx: u32, dt: f32) {
      pos[idx] = (pos[idx] + vel[idx] * dt) * 0.99;
    }
  `,
});
await integrate.run({ pos, vel }, { dt: 0.02 });
Device management, buffer sizing, pipeline creation, double buffering, dispatch, readbacks, error line-mapping — all handled by the library.
The same thing, with raw WebGPU
For honesty: here is the heavily condensed native equivalent (full version is ~150 lines; this excerpt omits error handling, resize, double buffering, staging readbacks and the render pipeline):
const adapter = await navigator.gpu.requestAdapter();
const device = await adapter.requestDevice();

// buffers — sizes and usages hand-computed
const pos = device.createBuffer({ size: 100_000 * 8, usage: GPUBufferUsage.STORAGE | GPUBufferUsage.COPY_DST | GPUBufferUsage.COPY_SRC });
const vel = device.createBuffer({ size: 100_000 * 8, usage: GPUBufferUsage.STORAGE | GPUBufferUsage.COPY_DST | GPUBufferUsage.COPY_SRC });

// hand-written WGSL, uniform struct aligned to 16 bytes by hand
const module = device.createShaderModule({ code: `...struct Params {...}...` });

const pipeline = device.createComputePipeline({ layout: 'auto', compute: { module, entryPoint: 'main' } });
const bindGroup = device.createBindGroup({ layout: pipeline.getBindGroupLayout(0), entries: [/* every binding, exact order */] });

function tick(dt) {
  const enc = device.createCommandEncoder();
  const pass = enc.beginComputePass();
  pass.setPipeline(pipeline);
  pass.setBindGroup(0, bindGroup);
  pass.dispatchWorkgroups(Math.ceil(100_000 / 64));
  pass.end();
  device.queue.submit([enc.finish()]);
}
// …plus: staging readbacks, device-lost handling, WGSL compile diagnostics,
// canvas resize — and a render pipeline before anything is visible.
With wgpu-kit, the kernel is the only code you write — and when WGSL fails
to compile, the error points at your line.
Entry points
| import | purpose |
|---|---|
wgpu-kit |
elementKernel core + Buffer / PingPong / rawKernel |
wgpu-kit/particles |
particle life: presets, adaptive world, live updates |
wgpu-kit/life |
Turing patterns / Physarum / Boids / Tentacles |
wgpu-kit/fields |
vector-field advection trails |
wgpu-kit/image |
GPU filter pipeline (blur/sharpen/edge/…) |
wgpu-kit/react |
<ParticleCanvas /> |
wgpu-kit/three |
three.js snapshot interop |
wgpu-kit/media |
canvas recording (webm/mp4) |
wgpu-kit/observe |
GPU timing / device diagnostics / canvas helpers |
wgpu-kit/vite |
WGSL kernel hot reload |
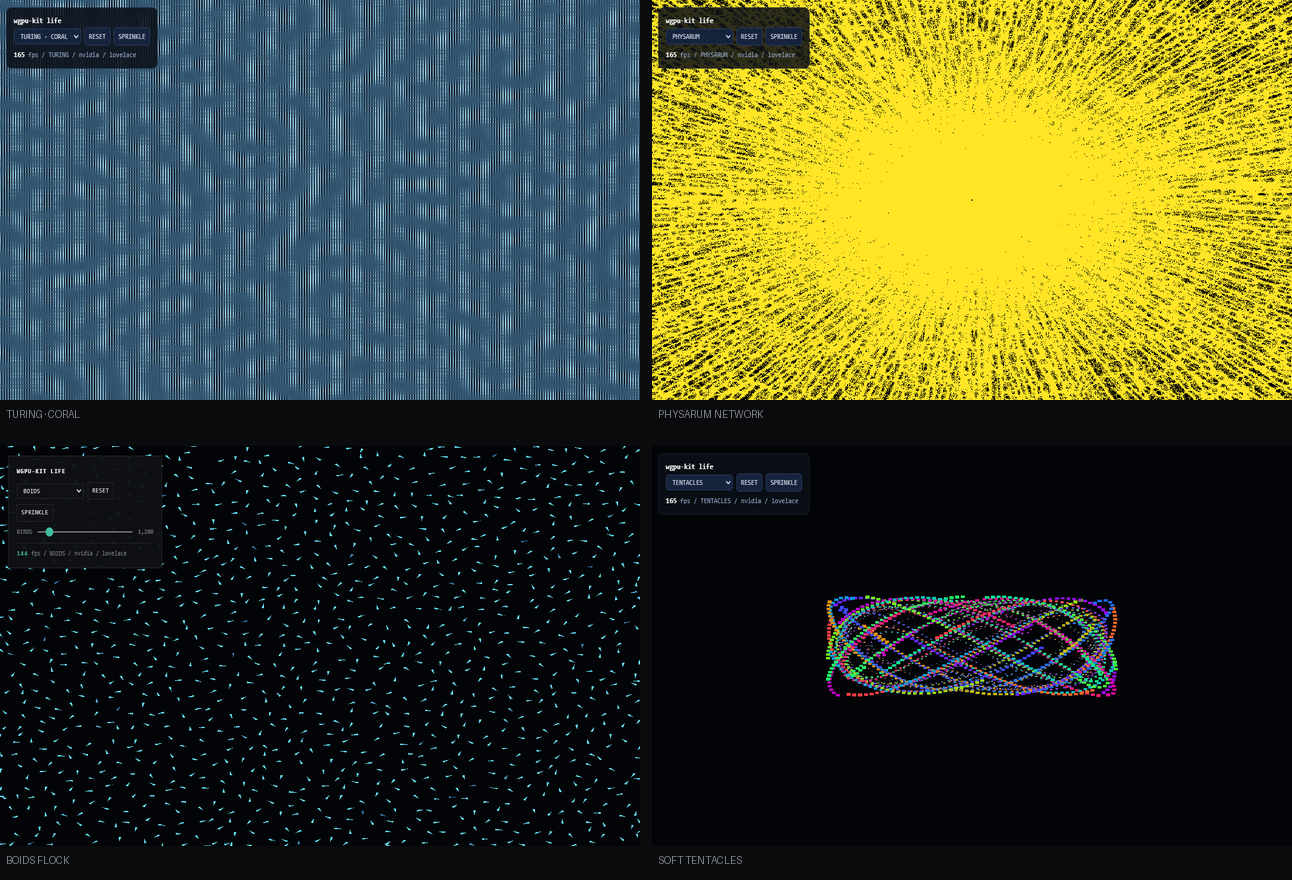
The life pack: Turing patterns / Physarum / Boids / Tentacles — open the demo.
Numbers (reproducible)
All fps numbers are visible frames — every tick() renders fresh state.
| metric | value | environment |
|---|---|---|
| particles end-to-end | 200,000 @ 122fps · 66,000 @ 144fps | RTX 4060 Laptop, playground |
| particle compute (grid) | 16k→262k flat, 3.0→4.4ms/frame | reproducible via npm run bench → docs/BENCHMARK.md |
| neighborhood algorithms | grid ~O(N), 8.5× faster than brute force at 66k | same-session A/B |
| bundle size | core gzip ~10kB (all entries share one context) | measured by npm run build |
Three design rules
- Level-2 works in 5 minutes, level-1 has no ceiling —
rawKerneland nativeGPUBufferescape hatches stay open; - Errors speak human — WGSL compile failures map back to your line numbers;
- Benchmarks are documentation — every published number is reproducible;
gzip budgets are enforced by
npm run build.
Verification
41+ automated probes run on a real GPU via a headless Chromium harness
(included: tests/ + scripts/verify.mjs) — including a physics
equivalence regression that fails the build if the neighborhood algorithms
(n2 / tiled / grid) ever produce divergent structures.
Support matrix
| browser | status |
|---|---|
| Chrome / Edge 113+ (incl. headless) | all validation runs here (RTX 4060, D3D backend) |
| Safari 18+ / Firefox | should work with WebGPU enabled; untested — issues welcome |
| WebGL2 / no WebGPU | no fallback (by design); detect.html can diagnose |